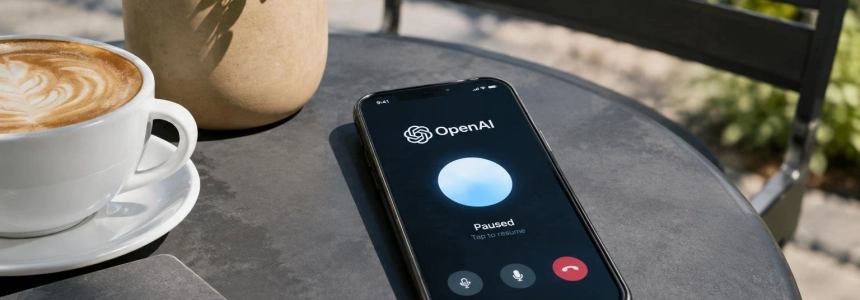
Standby reduces the rate to $0.02 per minute when an OpenAI WebRTC voice session is idle; time with active inference costs $0.05 per minute. The company has also added GPT-Live-1.1 to its API, with stated improvements in pronunciation, accent consistency, and multilingual transcription.
Both updates appear together in OpenAI’s November changelog update. AI Rank dates the API announcement to November 19, 2026. The new standby option is available for WebRTC sessions with both GPT-Live-1 and GPT-Live-1.1.
A voice update and a rate for silence
GPT-Live-1.1 can listen while speaking, according to OpenAI’s model page. Compared with GPT-Live-1, the company says it offers more accurate transcriptions and a more consistent voice and accent when conversing in different languages. The changelog update also highlights improved pronunciation in multilingual conversations.
Developers can select gpt-live-1.1 in the settings of an existing Live session. OpenAI recommends describing in natural language when a task should be delegated to the backend, for example for reasoning or tool use. Voice inference and backend work are not covered by a single rate: model and tool usage are charged separately.
“GPT-Live-1.1 is now available in the API. It speaks with more natural and consistent accents across languages, supports lower idle costs with a new standby option, and completes tasks even more reliably.”
— @OpenAIDevs, OpenAI developer account
The main operational update is Standby for WebRTC. Instead of keeping inference running throughout the entire pause, a session can stop it after a period with no incoming or outgoing transcriptions. If the user speaks again, inference resumes while preserving the session and conversation history.
| Session state | Stated rate | Condition |
|---|---|---|
| Active | $0.05 per minute | Inference is running |
| Standby | $0.02 per minute | Inference paused in a WebRTC session |
The rates apply to GPT-Live-1 and GPT-Live-1.1. According to AI Rank, session duration is billed by the second and is not rounded up to a full minute; backend model and tool usage are added separately. The lower rate therefore applies to the standby period, not the entire call or delegated tasks.
Silence triggers the pause, but the session stays open
The documented configuration lets you set a timeout of 5 to 60 seconds. When that interval passes without any transcriptions, the system enters Standby. If the limit is omitted, inference remains active after the first wake-up until the session ends, so the reduced rate is not automatically applied to subsequent silences.
To enable speech wake-up, the guide says to set session.wake_policy.type to speech. The session.idle_timeout_s parameter takes an integer between 5 and 60. You can also configure session.wake_policy.vad_threshold, with a value between 0 and 1 and a default value of 0.5; this threshold applies to the first wake-up and after each pause.
During Standby, the microphone and connection remain active, and the session ID does not change. When the user returns, the history is restored. The documentation warns that the first response to a brief utterance after the pause may take longer.
For long periods when there is no need to preserve the connection, the documentation recommends another option: close the session and open a new one when the user returns. Keeping it open in Standby is intended for pauses within a conversation that needs to continue with its context.
GPT-Live-1.1 had already arrived in ChatGPT
The API announcement is not the model’s first appearance. AB通信 reports that OpenAI had already been using it in ChatGPT Plus and Pro’s voice feature since October 15, 2026, and that rollout also included GPT-Live-1.1 Quip, a small variant. Availability in ChatGPT and the API release are separate announcements.
The Live API already offered GPT-Live-1, presented as an interface for duplex voice conversations that can continue while a backend model or agent handles reasoning and tools. In September, OpenAI said voice sessions cost $0.05 per minute, billed by the second, with backend and tool usage charged separately. Standby now adds a lower rate for paused inference.
OpenAI had also announced in November that outbound SIP calls were available to all organizations through the Live API. The connection to a phone number is made through each customer’s SIP provider. That capability can link the API to telephony, but the GPT-Live-1.1 announcement does not state that a SIP session has the Standby option: the cited documentation limits this configuration to WebRTC.
Multilingual improvements and latency that can vary
The model update focuses on how a conversation in multiple languages sounds and is transcribed. OpenAI says pronunciation and accent consistency have improved; the model description does not provide a specific accuracy figure for each language. AB通信 notes that the API’s voice list includes Harema and Shida for Japanese, as well as voice names for other languages published previously.
The stated improvement does not eliminate every trade-off of pausing: the first response after resuming may be delayed, according to the guide. In a call with frequent, brief pauses, the application therefore preserves the session and its history, but developers should consider this possible delay when choosing the idle timeout. The announcement does not provide a universal savings estimate; savings will depend on how long each session remains in Standby.
The immediate next step for those already using Live is to change the model ID and, if their integration uses WebRTC, configure the wake policy and idle timeout. The reduced rate applies while inference is paused; the WebRTC connection stays open until the application closes the session.
Sources: OpenAI Developers, OpenAI Developers, AI Rank, AB通信(abcompany)