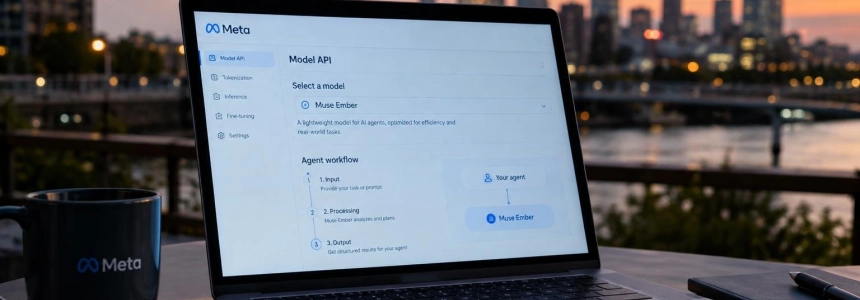
Meta launched Muse Ember, a lightweight model designed to handle repetitive tasks within agent workflows: tool calls, coding subtasks, request classification, data extraction, and reading lengthy documents. It has been available since Monday, November 9, in Muse Code and Meta Model API, with pricing starting at $0.10 per million input tokens.
Meta Superintelligence Labs presents it as its smallest and most efficient model to date. The idea is not to replace higher-capability models, but to divide the work: Muse Wonder or Muse Spark can plan and solve the more demanding parts, while Ember handles bounded tasks at high volume. In Meta’s words, “Muse Wonder plans, Muse Ember handles the volume.”
The model accepts text, images, audio, video, and PDFs, but generates text. Its context window reaches 1,048,576 tokens and it supports up to 524,288 output tokens. Meta positions it for processes such as analyzing contracts, reviewing code, or going through collections of files and records, as well as operating desktop applications based on screenshots.
An execution model, not the primary planner
Meta’s proposed architecture separates planning from execution. A larger model can determine how to approach a problem and then delegate repetitive actions to Ember. In a customer service example, the higher-capability model would define the rules for responding to an issue; Ember would then apply them to tens of thousands of cases.
Meta’s documentation describes more specific uses: running coding tasks and terminal commands delegated by a primary agent, chaining tool calls, routing each request to the appropriate system, and processing many images, files, or records in parallel. Batch-processing examples include classifying tickets, extracting fields, and captioning and sorting photos.
Ember supports computer-use capabilities, image understanding, tool calls, structured output, and grounding through searches. The API documentation notes that it shares the request format of Muse Spark, so in most examples, switching models involves changing the identifier. For complex coding problems solved in a single interaction, questions requiring extensive knowledge, or visual programming, Meta recommends Muse Spark or Muse Wonder.
The Muse family already included Spark, the mid-sized model launched in April; Glimmer, its open-source alternative introduced in August; and Wonder, the frontier model that arrived in October. Ember is the brand’s fourth model. Meta says it is the first trained with Muse Wonder Full, and links its launch to the goal announced when Wonder and Wonder Full were introduced: using them to develop specialized models.
Pricing, limits, and API access
The entry-level price is $0.10 per million input tokens, $0.004 per million cached input tokens, and $0.50 per million output tokens. These rates apply to requests with up to 200,000 input tokens. If a request exceeds that threshold, Meta charges the long-context rate for all tokens in the request, not just those above the limit: $0.30 per million input tokens, $0.012 per million cached tokens, and $1.50 per million output tokens.
The model is offered in standard mode through Meta Model API and also in Muse Code, both with pay-as-you-go and subscription options. The API does not have a Contributor variant: that mode, which offers reduced rates in exchange for permission to use submitted content and responses to train future models, is not available for Ember. In Muse Code, requests with more than 200,000 input tokens use up the plan’s included usage more quickly.
The model identifier is muse-ember-1.0. Meta’s documentation lists the Responses, Chat Completions, and Messages endpoints, although availability through Muse Code and Model API is announced directly in the product launch. Meta also publishes a limit of 3,000 requests and 4 million tokens per minute for the model, applied per team rather than per individual key.
Google Cloud includes Muse Ember 1.0 in its partner model catalog, but marks it as a preview version. Its listing indicates availability through the global endpoint, text and image input, and the same maximum context and output lengths. Meta’s documentation also lists audio, video, and PDF as supported input formats.
What the published tests show
Meta uses Artificial Analysis results to compare intelligence and cost per task. On the Intelligence Index, Ember scores 36 at the maximum reasoning level. The company says it matches Claude Haiku 5.5’s best score at approximately one-third the cost and outperforms GPT-6 Luna configurations. In the evaluation table, Ember scores 35.8 points at an estimated cost of $0.136 per task; Haiku scores 36.2 points at $0.411, and Luna scores 27.8 at $0.152.
At the xhigh level, Meta reports an Ember score of 33.9 and a cost of $0.116 per task. The company estimates that at the maximum level, each task costs around $0.14. These are estimates based on the model’s proposed rates, not prices independent of the number of tokens consumed.
Results also vary by test. On AutomationBench-AA, which evaluates end-to-end enterprise workflows, Ember scores 37.8%, compared with Luna’s 20.2% and Haiku’s 13.9%. On Agents’ Last Exam, it reaches 61.6%, ahead of Luna at 57.1% and Haiku at 57.0%. And on the Personal Superintelligence Index, Meta’s internal index of personal and knowledge work, it scores 46.8%; Haiku scores 36.1% and Luna 37.0%.
In coding, Ember scores 40.9% on Terminal-Bench 4.0, compared with Haiku’s 39.2% and Luna’s 16.4%, using each model’s best published configuration. On Coding Agent Index-AA, which measures coding in real agent environments, the scores are 46, 37, and 31, respectively. But Ember does not win in every area: on FrontierCode 2.0-AA, which judges engineering tasks based on whether the changes would be acceptable for integration, Haiku scores 34.9%, Ember 27.2%, and Luna 25.2%.
Multimodal tests offer another point of comparison. On GDP.pdf-AA, focused on professional work with lengthy documents, Ember and Luna tie at 22.8%; Haiku scores 20.8%. On PerceptionBench with tools, a detailed visual perception evaluation, Ember scores 80.6%, Haiku 78.6%, and Luna 62.8%.
On OSWorld 2.1, which measures desktop application use, Meta reports a partial reward of 69.5% for Ember and 68.9% for Haiku. Counting tasks completed in full, Ember reaches 33.8%, compared with Haiku’s 27.8% and Luna’s 17%. A separate run of Muse Spark 1.3 completed 39.25% of tasks, although the published comparison does not present that result as part of the same run.
Speed and enterprise work, according to its partners
Meta accompanied the launch with comments from companies that tested Ember. Yashodha Bhavnani, Box’s vice president of AI products, explained that the team used it to evaluate contracts clause by clause against a company’s negotiation rules and to screen candidates against a detailed profile. According to Bhavnani, the system could also identify borderline candidates who still qualified as alternates.
“On the Box AI Complex Work Eval, Muse Ember delivers impressive accuracy, speed and token efficiency. It can score a contract against a company's negotiation playbook clause by clause and land on the right overall risk rating, or screen candidates against a detailed brief and flag the borderline ones who still qualify as alternates. Muse Ember is a fast, efficient foundation for agents doing real work on enterprise content.”
— Yashodha Bhavnani, Box’s vice president of AI products
Saoud Rizwan, Cline’s founder, highlighted its use as a subagent for coding and document analysis. Konstantinos Papamiltiadis, Oracle’s senior vice president of global alliances, said its initial tests showed it could handle complex engineering tasks.
You.com shared figures from a coding test: according to Chak Pothina, head of inference, Ember completed all evaluated coding tasks with a p95 latency of 2.2 seconds, the lowest among the models tested. The company said this meant it was four to thirteen times faster than leading open-weight models and used 36% to 48% fewer output tokens. These results were reported by Meta’s partners, not in an independent evaluation included in the Artificial Analysis table.
Meta details its safety testing
Before launch, Meta evaluated Ember under its Meta Superintelligence Scaling Framework. The company says it examined chemical and biological, cybersecurity, and loss-of-control risks, and that the model fell below the framework’s high-risk thresholds in the categories assessed. It also says Ember received the same training and the same basic safety tests.
Meta adds that it studied how Ember behaves when acting on behalf of a user: whether it follows their instructions, handles sensitive information appropriately, resists hidden instructions on web pages, in documents, or in tool responses, and requests human intervention before high-impact actions. The company does not publish figures from these safety tests in the launch announcement.
For now, Meta positions Ember as an option for repetitive work at scale, with Muse Spark or Muse Wonder available for more difficult tasks. The company says it already has more efficient models in training and will share updates, but has not announced a date or further details about them.
Sources: TechCrunch, The New Stack, Meta AI Research, Meta Model API, Meta Model API, Google Cloud Documentation, Meta Model API