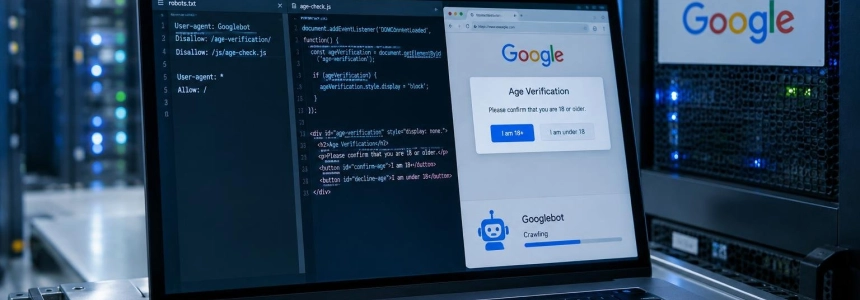
Googlebot can stop rendering an age verification popup if the resource that displays it is blocked through robots.txt. Google’s John Mueller explained two ways to do this on Reddit: prevent crawling of the external domain that serves the popup, or block the JavaScript file that loads it from the site itself. The condition is that the page must continue to load correctly when the bot cannot access those resources.
The clarification responds to a question about a hypothetical site that incorporates a popup hosted on another domain through an API. The question asked whether a disallow rule in that external domain’s robots.txt would prevent Google from seeing the notice, which must be shown to human visitors for legal reasons. Mueller replied that, generally, it would.
Two ways to prevent Googlebot from loading the popup
The first option is to act on the domain hosting the embedded content. If the popup provider blocks crawling in its robots.txt, Googlebot cannot obtain those resources and cannot use them when rendering the page. This can happen whether the content is incorporated through an iframe or the page calls a script hosted on the external domain.
Mueller noted that this mechanism is also seen with advertising services: Googlebot may try to request resources during rendering, even though it does not crawl them as standalone pages. If robots.txt prevents the request, the content is unavailable for that rendering. In the case of the age verification popup, the intended effect would be for the bot not to load it.
The other alternative is to block the specific file that inserts the popup from the site itself. Mueller used a dedicated script as an example, with a name such as load-verification-popup.js. By disallowing that file in the site’s robots.txt, the script is not loaded during rendering. He explained that this approach is less common and would be necessary if the site owner cannot modify the external domain’s robots.txt.
“That would generally work. If you’re using a specific JS script file to do this, you could also disallow that specific javascript file via robots.txt. (If you only have one JS file that does a bunch of things, I wouldn’t do that”
— John Mueller, Google
The warning concerns files that perform more than one task. If the same JavaScript controls other page functions in addition to displaying the notice, blocking it may prevent Googlebot from obtaining resources needed to render the page. Mueller’s recommendation applies only to the specific script that loads the popup; his response does not endorse indiscriminately blocking shared files.
The page must work without the blocked resource
In his subsequent explanation, Mueller emphasized that the site must continue to load when Googlebot cannot access the blocked resources. For a popup such as an age verification notice, he said this normally should not be a problem. The practical distinction is between removing an isolated element from rendering and blocking a resource on which other parts of the page depend.
Therefore, the fact that a popup is visible to users does not, in this specific case, require Googlebot to be able to download it. But this approach depends on the remaining content still being available and the rule affecting the right resource. If the site blocks a JavaScript file that also serves other functions, rendering may be incomplete.
The question posted on Reddit described a hypothetical scenario: a site called websiteA.com displayed a popup hosted on verificationpopup.com for legal reasons, embedded through an API. The person asking wanted to know whether a disallow directive in verificationpopup.com’s robots.txt file would prevent Google from rendering the notice. Mueller first answered that it would normally work, then detailed the two locations where the block could be applied.
The context: from unblocking resources to allowing exceptions
The question comes against the backdrop of a shift in crawling practices. In SEO’s early years, some professionals blocked JavaScript and CSS to reduce crawl budget consumption and facilitate indexing. Later, when Google began rendering pages, it asked site owners to allow Googlebot to download resources that users could see.
According to the context reported by Search Engine Journal and SERP Journal, some sites that kept important resources blocked temporarily lost rankings during that transition. That history explains why the question about a legally required popup was not trivial: the general instruction to allow visible resources could seem incompatible with deliberately hiding an element from the bot.
Mueller’s response narrows the scope of the case. It does not present blocking as a general rule for hiding content from Google, but as a technical possibility for specific resources, provided the site continues to render. SERP Journal also highlights the caution about scripts that perform multiple tasks. Brandon Lazovic likewise summarizes the advice as an option to block the popup’s domain or the file that loads it, subject to the same condition that the page must continue to work.
robots.txt does not guarantee that a URL will disappear from Google
Google’s developer documentation distinguishes between blocking the crawling of a URL and preventing it from appearing in search results. robots.txt tells crawlers which URLs they can request and is used primarily to manage traffic. It is not a mechanism designed to prevent a page from appearing on Google.
Google explains that a blocked URL may still appear in search results if other sites link to it, even if the search engine has not crawled its content. To prevent a page from appearing, the documentation recommends using noindex or protecting it with a password, depending on the case. This limitation is separate from Mueller’s point: here, the issue is preventing Googlebot from obtaining a resource during rendering, not removing a URL from search results.
The documentation also allows resources—such as images, scripts, or style files—to be blocked when doing so does not significantly harm the page. It warns against blocking them if that makes it harder for Google to analyze pages that depend on those resources. It also notes that trusted crawlers follow robots.txt rules, but they do not require all web bots to respect them.
Mueller’s response confirms that a popup can be kept out of Googlebot’s rendering through a rule on the domain serving it or by blocking its dedicated script. The open question is whether Google will incorporate this selective allowance into broader official guidance; SERP Journal raises that possibility as something to watch, not as an announced change.
Sources: Search Engine Journal, Google for Developers, SERP Journal, Brandon Lazovic